Monday, 17 December 2018

Extracting insights from IoT data using the cold path data flow

This blog continues our coverage of the solution guide published by Microsoft’s Industry Experiences team. The guide covers the following components:

◈ Ingesting data
◈ Hot path processing
◈ Cold path processing
◈ Analytics clients

We already covered the recommendation for processing data for an IoT application in the solution guide and suggested using Lambda architecture for data flow. To reiterate the data paths:

◈ A batch layer (cold path) stores all incoming data in its raw form and performs batch processing on the data. The result of this processing is stored as a batch view. It is a slow-processing pipeline, executing complex analysis, combining data from multiple sources over a longer period (such as hours or days), and generating new information such as reports and machine learning models.

◈ A speed layer and a serving layer (warm path) analyzes data in real time. This layer is designed for low latency, at the expense of accuracy. It is a faster-processing pipeline that archives and displays incoming messages, and analyzes these records, generating short-term critical information and actions such as alarms.

This blog post covers the cold path processing components of the solution guide.

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

We have covered timeseries analysis with Azure Time Series Insights (TSI) in detail in the solution guide. It is an analytics, storage, and visualization service for timeseries data. Please read the relevant section for the use of TSI.

As you may remember from previous blog posts, we are using the sample data published by the NIST SMS Test Bed endpoint. Our previous posts ended with the data pushed to separate Azure Event Hubs for “events” and “samples” data records.

Before we begin the rest of the discussion, we would like to emphasize that the solution of an “analytics” problem is dependent on each plant, line, machine, and so on. The data must be available and be what the business needs. We will cover two different approaches for organizing the data, but they are not exhaustive, and are meant as examples only.

Storing the raw data

Our sample implementation has a basic set of Azure Stream Analytics queries that takes the incoming data stream from the Event Hubs that the raw data is posted to and copies it into Azure Storage blobs and tables. As an example, the queries look like the following:

SELECT
     *
INTO
     [samplesTable]
FROM
     [EventHubIn]

One table is for samples and another is for events. As we were flattening the incoming data in the custom component, we added a property for the hour window the incoming data stream was in, using the following C# code snippet to help us more easily organize the data on the processing pipelines:

HourWindow =

   new DateTime(
       sample.timestamp.Year,
       sample.timestamp.Month,
       sample.timestamp.Day,
       sample.timestamp.Hour,
       0,
       0),

This data record field is especially useful in organizing the records on the Azure Storage Table, simply by using it as the partition key. We are using the sequence number of the incoming record as the row key. The object model for the storage tables are covered in the documentation, “Understanding the Table Service Data Model.” 

The Azure Blob Storage blobs generated by the ASA job are organized in containers for each hour, as a single blob for the data for the hour, in the comma separated values (CSV) format. We will be using these in the future for artificial intelligence (AI) needs.

Loading data into Azure SQL Database
We will be covering a basic way to incrementally load the records to an Azure SQL Database and later discuss potential ways for further processing them to create new aggregations and summary data.

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

Our goal is to provide a barebones approach to show how data can flow into data stores and demonstrate the technologies useful for this. Any analytics solution depends heavily on the context and requirements, but we will attempt to provide basic mechanisms to demonstrate the related Azure services.

Azure Data Factory (ADF) is a cloud integration service to compose data storage, movement, and processing services in automated data pipelines. We have a simple ADF pipeline that demonstrates the incremental loading of a table using a storage table as the source.

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

The pipeline has a lookup activity that performs the following query on the SQL Database:

select
     CONVERT(
         char(30),
         case when  max(SampleTimestamp) is null then '1/1/2010 12:00:00 AM'
             else max(SampleTimestamp) end, 126) as LastLoad
from [Samples]

The style used in the CONVERT function, 126, denotes the timestamp value to be formatted as “yyyy-mm-ddThh:mi:ss.mmm,” which matches the string representation of the partition key value on the storage table. The query returns the last record that was transferred to the SQL database. We can then pass that value to the next activity to query the table storage to retrieve the new records.

Next is a “Copy Data” activity, which simply uses the returned value from the lookup activity, which is the value of the “LastLoad,” and makes the following table query for the source. Please refer to Querying Tables and Entities for details on querying storage tables.

SampleTimestamp gt datetime'@{formatDateTime(activity('LookupSamples').output.FirstRow.LastLoad, 'yyyy-MM-ddThh:mm:ss.fffZ')}'

Later, this activity maps the storage table columns (properties) to SQL Database table columns. This pipeline is scheduled to run every 15 minutes, thus incrementally loading the destination SQL Database table.

Processing examples

Further processing the raw data depends on the actual requirements. This section covers two potential approaches for processing and organizing the data to demonstrate the capabilities.

Let’s first start looking at the data we collect to discover the details. Notice that the raw data on the samples table is in the form of name/value pairs. The first query will give us the different sample types recorded by each machine.

SELECT DeviceName, ComponentName, SampleName, COUNT(SampleSequence) AS SampleCount
FROM Samples
GROUP BY DeviceName, ComponentName, SampleName 
ORDER BY DeviceName ASC, ComponentName ASC, SampleName ASC, SampleCount DESC

We observe there are eight machines, and each one is sending different sets of sample types. Following is the partial result of the preceding query. We analyzed the result a bit further in Microsoft Excel to give an idea of the relative counts of the samples:

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

We may conclude that the best way to aggregate and summarize the results is first to organize the results by machine — for example, a raw data table per machine.

We will go step by step to demonstrate the concepts here. Some readers will surely find more optimized ways to implement some queries, but our goal here is to provide clear examples that demonstrate the concepts.

We may wish to process the data further by first transposing the raw data, which is in name/value pairs, as follows:

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

We can use the following query to create a new table and transpose whole rows. This query assumes that we do not differentiate any of the components and see the machine as a whole:

; WITH Machine08SamplesTransposed AS
(
     SELECT * FROM
     (
         SELECT  SampleTimestamp, sampleName, CAST(sampleValue AS NUMERIC(20,3)) AS sampleValueNumeric
         FROM Samples
         WHERE
             DeviceName = 'Machine08' and ISNUMERIC(sampleValue) != 0
     ) AS S
    
     PIVOT(
         MAX(sampleValueNumeric)
         FOR SampleName IN ([S2temp],
             [Stemp],
             [Zabs],
             [Zfrt],
             [S2load],
             [Cfrt],
             [total_time],
             [Xabs],
             [Xload],
             [Fact],
             [Cload],
             [cut_time],
             [Zload],
             [S2rpm],
             [Srpm],
             [auto_time],
             [Cdeg],
             [Xfrt],
             [S1load])
         ) AS PivotTable
         )

SELECT * INTO Machine08Samples 
FROM Machine08SamplesTransposed

We can bring this query into the ADF pipeline by moving it into a stored procedure with a parameter to query the raw table so that only the latest loaded rows are brought in, and modifying “SELECT * INTO …” to “INSERT * INTO …”. We recommend relying on stored procedures as much as possible to use SQL database resources efficiently.

The resulting table looks like the following (some columns removed for brevity).

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

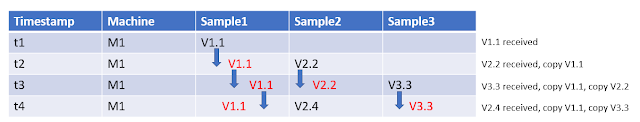
One way to process this interim data set is to fill in the null values of samples from the last received value, as shown below.

We should emphasize that we are not recommending this solution for every business case and for every sample value. This approach makes sense for the values that are meaningful together. For example, in a certain case, grouping Fact (actual path feed-rate) and Zfrt (Z axis feed-rate) may make sense. However, for another case Xabs (absolute position on X axis) and Zfrt on one record, grouped this way, may not make sense. Grouping of the sample values must be done on a case-by-case basis, depending on the business need.

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

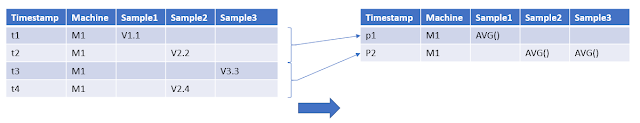
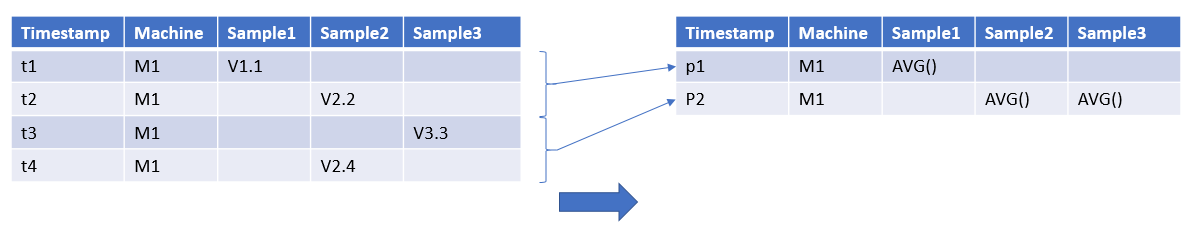
Or another way is to put the individual records into time buckets, and apply an aggregate function in that group:
Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

Let’s give a small example for achieving the first option. In the preceding example, we received V1.1 at t1, and received V2.2 at t2. We want to fill in the Sample1 value for t2 with t1s, V1.1.

;WITH NonNullRank AS
(
     SELECT SampleTimestamp, S2temp,  cnt = COUNT(s2temp) OVER (ORDER BY SampleTimestamp)
     FROM Machine08Samples
),

WindowsWithNoValues AS
(
     SELECT SampleTimestamp, S2temp, 
r = ROW_NUMBER() OVER (PARTITION BY cnt ORDER BY SampleTimestamp ASC) - 1
     FROM NonNullRank
)

SELECT SampleTimestamp, S2temp,
S2tempWithValues= ISNULL(S2temp, LAG(S2temp, r) OVER (ORDER BY SampleTimestamp ASC))
FROM WindowsWithNoValues

When we dissect the preceding queries, the first common table expression (CTE), NonNullRank, gives us the rank of the non-null values of S2temp sample values among the received data records.

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

The second CTE, WindowsWithNoValues, gives us windows of samples with the received value at the top, and the order of null values within the windows (column r).

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

The concluding query fills in the null values using the LAG analytic function by bringing in the received value from the top of the window to the current row.

Azure Certification, Azure Tutorial and Materials, Azure Learning, Azure Live

The second option we mentioned previously is to group the received values and apply an aggregate function within the group.

;WITH With30SecondBuckets AS
(
     SELECT *,
(dateadd(second,(datediff
(second,'2010-1-1',[SampleTimestamp])/(30))*(30),'2010-1-1'))
AS  [SampleTimestamp30Seconds]
     FROM Machine08Samples
)

SELECT SampleTimestamp30Seconds, AVG(S2Temp)
FROM With30SecondBuckets GROUP BY SampleTimestamp30Seconds
ORDER BY SampleTimestamp30Seconds

We can put these queries in a stored procedure to generate new aggregate and summary tables as necessary to be used by the analytics solution.

We would like to repeat our opening argument here once more. The solution to an analytics problem depends on the available data, and what business needs. There may not be one single solution, but Azure provides many technology options for implementing a given solution.

Sunday, 16 December 2018

Streamlined IoT device certification with Azure IoT certification service

For over three years, we have helped customers find devices that work with Azure IoT technology through the Azure Certified for IoT program and the Azure IoT device catalog. In that time, our ecosystem has grown to one of the largest in the industry with more than 1,000 devices and starter kits from over 250 partners.

Today, we are taking steps to further to grow our device partner ecosystem with the release of Azure IoT certification service (AICS), a new web-based test automation workflow, which is now generally available. AICS will significantly reduce the operational processes and engineering costs for hardware manufacturers to get their devices certified for Azure Certified for IoT program and be showcased on the Azure IoT device catalog.

Over the past year, we’ve made significant improvements to the program such as improving the discovery of certified devices in the Azure Certified for IoT device catalog and expanding the program to support Azure IoT Edge devices. The goal of our certification program is simple – to showcase the right set of IoT devices for our customers’ industry specific vertical solutions and simplify IoT device development.

AICS is designed and engineered to help achieve these goals, delivering on four key areas listed below:

Consistency


AICS is a web-based test automation workflow that can work on any operating systems and web browser. AICS communicates with its own set of Azure IoT Hub instances to automatically validate against devices to Azure IoT Hub bi-directional connectivity and other IoT Hub primitives.

Previously, hardware manufacturers had to instantiate their own IoT Hub using their Azure subscription in order to get certified. AICS not only eliminates Azure subscription costs for our hardware manufacturers, but also streamlines the certification processes through automation. These changes accrue to driving more quality and consistency compared to the manual processes that were in place before.

Additional tests


The certification program for IoT devices has always validated against bi-directional connectivity from device to IoT Hub cloud service (namely device-to-cloud and cloud-to-device). As IoT devices become more intelligent to support more capabilities, we have now expanded our program to support validation of device twins and direct methods IoT Hub primitives. AICS validate these capabilities and Azure IoT device catalog will correspondingly showcased them as well that make it easy for device seekers to build IoT solutions on these rich capabilities.

The screenshot below shows customizable test cases. By default, device-to-cloud is the required test and all others are optional. This new requirement allows constrained devices such as microcontrollers to be certified.

Azure Certification, Azure Learning, Azure Tutorial and Materials, Azure Guides

The screenshot below shows how tested capabilities are shown on the device description page in the device catalog.

Azure Certification, Azure Learning, Azure Tutorial and Materials, Azure Guides

Flexibility


Previously, hardware manufacturers were required to use the Azure IoT device SDK to build an app to establish connectivity from device(s) to cloud managed by Azure IoT Hub services. Based on partners’ feedback, we now support devices that do not use Azure IoT device SDK to establish connectivity to Azure IoT Hub, for example, devices that use the IoT Hub resource provider REST API to create and manage Azure Hub programmatically or hardware manufacturers opt to use other device SDK equivalent to establish connectivity.

In addition, AICS allows hardware manufacturers to configure the necessary parameters for customized test cases such as number of messages of telemetry data sent from the devices.

The screenshot below illustrates an example page that shows the ability to configure each test case.

Azure Certification, Azure Learning, Azure Tutorial and Materials, Azure Guides

Simplicity


Finally, we have made investments to design a user experience that is simple and intuitive to hardware manufacturers. For example, in the device catalog, we have streamlined the process from device registration to running the validations using AICS through a simple wizard driven flow. Hardware developers can easily troubleshoot failed tests through detailed logs that improves diagnose-ability.

Because it’s a web-based workflow, serviceability of AICS is so simple that hardware manufacturers are not required to deploy any standalone test kits (no .exe, .msi, etc.) locally on their devices, which tend to become outdated over time.

The screenshot below shows each test case run. Log files show the test pass/fail along with raw data sent from device to cloud. The submit button only shows up when all the test cases selected pass. Once the tests are complete, we will review the results and notify the submitter of additional steps to complete the entire certification process.

Azure Certification, Azure Learning, Azure Tutorial and Materials, Azure Guides

Friday, 14 December 2018

Taking a closer look at Python support for Azure Functions

Azure Functions provides a powerful programming model for accelerated development and serverless hosting of event-driven applications. Ever since we announced the general availability of the Azure Functions 2.0 runtime, support for Python has been one of our top requests. At Microsoft Connect() last week, we announced the public preview of Python support in Azure Functions. This post gives an overview of the newly introduced experiences and capabilities made available through this feature.

What's in this release?


With this release, you can now develop your Functions using Python 3.6, based on the open-source Functions 2.0 runtime and publish them to a Consumption plan (pay-per-execution model) in Azure. Python is a great fit for data manipulation, machine learning, scripting, and automation scenarios. Building these solutions using serverless Azure Functions can take away the burden of managing the underlying infrastructure, so you can move fast and actually focus on the differentiating business logic of your applications. Keep reading to find more details about the newly announced features and dev experiences for Python Functions.

Powerful programming model


The programming model is designed to provide a seamless and familiar experience for Python developers, so you can import existing .py scripts and modules, and quickly start writing functions using code constructs that you're already familiar with. For example, you can implement your functions as asynchronous co-routines using the async def qualifier or send monitoring traces to the host using the standard logging module. Additional dependencies to pip install can be configured using the requirements.txt format.

Azure Functions, Microsoft Tutorial and Material, Azure Guides, Azure Certification

With the event-driven programming model in Functions, based on triggers and bindings, you can easily configure the event that'll trigger the function execution and any data sources that your function needs to orchestrate with. Common scenarios such as ML inferencing and automation scripting workloads benefit from this model as it helps streamline the diverse data sources involved, while reducing the amount of code, SDKs, and dependencies that a developer needs to configure and work with at the same time. The preview release supports binding to HTTP requests, timer events, Azure Storage, Cosmos DB, Service Bus, Event Hubs, and Event Grid. Once configured, you can quickly retrieve data from these bindings or write back using the method attributes of your entry point function.

Azure Functions, Microsoft Tutorial and Material, Azure Guides, Azure Certification

Easier development


As a Python developer, you don't need to learn any new tools to develop your functions. In fact, you can quickly create, debug and test them locally using a Mac, Linux, or Windows machine. The Azure Functions Core Tools (CLI) will enable you to get started using trigger templates and publish directly to Azure, while automatically handling the build and configuration for you.

Azure Functions, Microsoft Tutorial and Material, Azure Guides, Azure Certification

What's even more exciting is that you can use the Azure Functions extension for Visual Studio Code for a tightly integrated GUI experience to help you create a new app, add functions and deploy, all within a matter of minutes. The one-click debugging experience will let you test your functions locally against real-time Azure events, set breakpoints, and evaluate the call stack, simply on the press of F5. Combine this with the Python extension for VS Code, and you have a best-in-class auto-complete, IntelliSense, linting, and debugging experience for Python development, on any platform!

Azure Functions, Microsoft Tutorial and Material, Azure Guides, Azure Certification

Linux based hosting


Functions written in Python can be published to Azure in two different modes, Consumption plan and the App Service plan. The Consumption plan automatically allocates compute power based on the number of incoming events. Your app will be scaled out when needed to handle a load, and scaled back down when the events become sparse. Billing is based on the number of executions, execution time and memory used, so you don't have to pay for idle VMs or reserved capacity in advance.

In an App Service plan, dedicated instances are allocated to your function which means that you can take advantage of features such as long-running functions, premium hardware, Isolated SKUs, and VNET/VPN connectivity while still being able to leverage the unique Functions programming model. Since using dedicated resources decouples the cost from the number of executions, execution time, and memory used, the cost is capped to the number of instances you've allocated to the plan.

Underneath the covers, both hosting plans run your functions in a docker container based on the open source azure-function/python base image. The platform abstracts away the container, so you're only responsible for providing your Python files and don't need to worry about managing the underlying Azure Functions and Python runtime.

Tuesday, 11 December 2018

Deploying Apache Airflow in Azure to build and run data pipelines

Apache Airflow is an open source platform used to author, schedule, and monitor workflows. Airflow overcomes some of the limitations of the cron utility by providing an extensible framework that includes operators, programmable interface to author jobs, scalable distributed architecture, and rich tracking and monitoring capabilities. Since its addition to Apache foundation in 2015, Airflow has seen great adoption by the community for designing and orchestrating ETL pipelines and ML workflows. In Airflow, a workflow is defined as a Directed Acyclic Graph (DAG), ensuring that the defined tasks are executed one after another managing the dependencies between tasks.

A simplified version of the Airflow architecture is shown below. It consists of a web server that provides UI, a relational metadata store that can be a MySQL/PostgreSQL database, persistent volume that stores the DAG files, a scheduler, and worker process.

Data Warehouse, Monitoring, Apache, Azure Certifications, Azure Study Materials, Azure Tutorial and Material

The above architecture can be implemented to run in four execution modes, including:

◈ Sequential Executor – This mode is useful for dev/test or demo purpose. It serializes the operations and allows only a single task to be executed at a time.
◈ Local Executor – This mode supports parallelization and is suitable for small to medium size workload. It doesn’t support scaling out.
◈ Celery Executor – This is the preferred mode for production deployments and is one of the ways to scale out the number of workers. For this to work, an additional celery backend which is a RabbitMQ or Redis broker is required for coordination.
◈ Dask Executor – This mode also allows scaling out by leveraging the Dask.distributed library, allowing users to run the task in a distributed cluster.

The above architecture can be implemented in Azure VMs or by using the managed services in Azure as shown below. For production deployments, we recommend leveraging managed services with built-in high availability and elastic scaling capabilities.

Data Warehouse, Monitoring, Apache, Azure Certifications, Azure Study Materials, Azure Tutorial and Material

Puckel's Airflow docker image contains the latest build of Apache Airflow with automated build and release to the public DockerHub registry. Azure App Service for Linux is integrated with public DockerHub registry and allows you to run the Airflow web app on Linux containers with continuous deployment. Azure App Service also allow multi-container deployments with docker compose and Kubernetes useful for celery execution mode.

We have developed the Azure QuickStart template, which allows you to quickly deploy and create an Airflow instance in Azure by using Azure App Service and an instance of Azure Database for PostgreSQL as a metadata store.

Data Warehouse, Monitoring, Apache, Azure Certifications, Azure Study Materials, Azure Tutorial and Material

The QuickStart template automatically downloads and deploys the latest Docker container image from puckel/docker-airflow and initializes the database in Azure Database for PostgreSQL server as shown in the following graphic:

Data Warehouse, Monitoring, Apache, Azure Certifications, Azure Study Materials, Azure Tutorial and Material

The environment variables for the Airflow docker image can be set using application settings in Azure App Service as shown in the following graphic:

Data Warehouse, Monitoring, Apache, Azure Certifications, Azure Study Materials, Azure Tutorial and Material

The environment variables used in the deployment are:

◈ AIRFLOW__CORE__SQL_ALCHEMY_CONN – Sets the connection string for web app to connect to Azure Database for PostgreSQL.
◈ AIRFLOW__CORE__LOAD_EXAMPLES – Set to true to load DAG examples during deployment.

The application setting WEBSITES_ENABLE_APP_SERVICE_STORAGE is set to true which can be used as a persistent storage for DAG files accessible to scheduler and worker container images.

After it is deployed, you can browse the web server UI on port 8080 to see and monitor the DAG examples as shown in the following graphic:

Data Warehouse, Monitoring, Apache, Azure Certifications, Azure Study Materials, Azure Tutorial and Material

Next steps


You are now ready to orchestrate and design data pipelines for ETL and machine learning workflows by leveraging the Airflow operators. You can also leverage Airflow for scheduling and monitoring jobs across fleet of managed databases in Azure by defining the connections as shown below.

Data Warehouse, Monitoring, Apache, Azure Certifications, Azure Study Materials, Azure Tutorial and Material

If you are looking for exciting challenge, you can deploy the kube-airflow image with celery executor with Azure Kubernetes Services using helm charts, Azure Database for PostgreSQL, and RabbitMQ. Let us know if you have developed it and we would be happy to provide link it to this blog.

Friday, 7 December 2018

New automated machine learning capabilities in Azure Machine Learning service

We are excited to announce the new automated machine learning (automated ML) capabilities. Automated ML allows you to automate model selection and hyperparameter tuning, reducing the time it takes to build machine learning models from weeks or months to days, freeing up more time for them to focus on business problems. The making of automated ML was driven by our commitment to improve the productivity of data scientists and democratize AI. By simplifying machine learning, automated ML enables domain experts in the businesses to rapidly build and deploy machine learning solutions.

In this blog post, we will:

1. Highlight the new automated ML capabilities of that are available today as part of Azure Machine Learning service
2. Walk you through the motivation, underlying technology, and principles behind automated ML


New capabilities


Since the preview of Azure Machine Learning service just a couple of months ago, we have added many compelling capabilities.

Training infrastructure

Machine learning training jobs are very compute intensive, and training time is highly dependent on the size of the dataset and the type of algorithm. As a result, training is often a bottleneck and the ability to complete jobs quickly enables data scientists to iterate fast. With automated ML, you have many choices for compute infrastructure that you can run your training jobs with. Start by running your jobs on your local machine and scale up and out using the Azure cloud.

Azure Machine Learning compute

When you are ready to scale, automated ML enables you to run your training jobs in the Azure Cloud by scaling up as well as running multiple training jobs in parallel using Azure Machine Learning compute or Azure Databricks clusters. With Azure Machine Learning compute, you can setup a cluster of Azure Virtual Machines to run your training jobs in parallel. Autoscaling ensures that virtual machines are shut down when the training jobs are complete, saving you costs.

Azure Databricks (preview)

Azure Databricks is a managed Spark offering on Azure that is popular with big data processing. With automated machine learning on Azure Databricks, customers who use Azure Databricks can now use the same cluster to run automated machine learning experiments, allowing data to remain in the same place. You can leverage the local worker nodes with autoscale and auto termination capabilities.

Local computer

Often data scientists start training machine learning models on their local computer with down sampled data. Constraints such as the data governance and security policies of organizations may require data to stay on-premises. With automated ML, you can run your training jobs entirely on your local machine without data ever leaving your computer, complying with data security and protection needs.

Data pre-processing and featurization

Data Scientists spend a large percentage of their time on data cleaning, transformation, and generating new features. Automated ML simplifies many of these data pre-processing tasks by automatically transforming categorical features into one hot encoding, imputing missing values and rows, generating new date time features, and more.

Visual charts

Automated ML comes with rich visual charts such as a leaderboard of all the candidate models built by automated ML. Also included are many different metrics of each model and charts to help visualize/compare model performance such as confusion matrices. Visual charts are integrated into Jupyter notebooks via an extension so that you never have to leave the comfortable notebook experience. The charts are also available on Azure Portal for those who use a different IDE.

Forecasting (preview)

In addition to classification and regression, we now support forecasting. Time series forecasting is a common problem and has applications in many industries. For example, retail companies want to forecast future product sales and energy utilities want to forecast power consumption demand. It is critical to ensure model tuning takes into consideration windows of time and aggregation to tune a model for optimal performance. When using the forecasting capability, automated machine learning optimizes our pre-processing, algorithm selection and hyperparameter tuning to recognize the nuances of time series datasets. Our service expands our support for feature engineering with greater focus on things like grain index featurization and grouping and missing row imputation to provide greater model performance and accuracy.

Model Explain Ability (preview)

Most businesses run on trust and being able to open the ML “black box” helps build transparency and trust.  In heavily regulated industries like healthcare and banking, it is critical to comply with regulations and best practices.  One key aspect of this is understanding the relationship between input variables (features) and model output.  Knowing both the magnitude and direction of the impact each feature (feature importance) has on the predicted value helps better understand and explain the model. With model explain ability, we enable you to understand feature importance as part of automated ML runs.

Region availability

Azure Machine Learning service is available in many regions in U.S (east and west coast), Europe, Asia and Australia. Having automated ML available in a region near you will help reduce the network latency. If your data is subject to data sovereignty and governance rules, you can choose to use automated ML that is available in your geography to adhere to these requirements.

Why automated machine learning?


Machine learning is complex

Developing machine learning solutions is complex, tedious and time consuming. The typical machine learning lifecycle consists of four parts: business understanding, data acquisition, modeling, and operationalization. Every Machine Learning solution should start with the business problem you are working to solve followed by acquiring and exploring the data that is needed.

Azure Certification, Azure Guides, Azure Tutorial and Material, Azure Machine Learning Service

In the feature engineering part of the modeling stage, you need to transform the input data via techniques such as removing nulls, rescaling, selecting for features, and/or generating new features. Next, you choose which machine learning algorithm is most suitable - a support vector machine (SVM), logistic regression, or a tree-based classifier? What parameter values should be used for the chosen algorithm (ex. the max depth and min split count for a tree-based classifier)? And many more. Just look at this “simple” tutorial chart from the scikit-learn machine learning library to see the complexity of algorithm selection:

Azure Certification, Azure Guides, Azure Tutorial and Material, Azure Machine Learning Service

In short, data scientists and developers face a series of sequential and interconnected decisions along the way to achieving "magical" machine learning solutions. Ultimately, all these decisions will determine the accuracy of the machine learning pipeline – it comes down to the combination of data pre-processing / feature engineering steps, learning algorithms, and hyperparameter settings that go into each machine learning solution.

Due to this variability, data scientists typically build several models with different combinations of features, learners and hyper parameters. These models are then evaluated to optimal accuracy and the most suitable is selected. Building multiple models and evaluating them is tedious and often takes many weeks. When machine learning solutions need to be updated as data evolves, data scientists would need to repeat the same feature engineering, model training and evaluation process.

Simplifying machine learning

But what if a developer or data scientist could access an automated service that identifies the best machine learning pipelines for their labelled data? The Automated ML capability in the Azure Machine Learning service provides this solution. Automated ML empowers users, with or without data science expertise, to identify an end-to-end machine learning pipeline for any problem, achieving a high quality machine learning model while spending far less of their time. It enables a significantly larger number of experiments to be run, resulting in faster iteration towards production-ready solutions.

Azure Certification, Azure Guides, Azure Tutorial and Material, Azure Machine Learning Service

Microsoft is committed to democratizing AI through our products. By simplifying and removing the need to tune models, hyperparameters manually, we are boosting the productivity of the users. By making automated ML available through the Azure Machine Learning service, we're empowering data scientists and organizations to build, deploy and manage the machine learning life cycle from end to end.

If you are new to data science, automated ML will help you get started quickly. Simplify the machine learning model building process by abstracting away the complexity of feature engineering, algorithm selection and hyperparameter tuning. This will enable more people in your organization to leverage machine learning and most importantly allow domain experts to rapidly prototype ML solutions and validate their hypothesis before involving data scientists.

If you are an experienced data scientist, automated ML will let you improve productivity and save time by eliminating the need to manually perform the tedious and repetitive tasks of feature engineering, algorithm selection and hyperparameter tuning. You can even start by generating a model with automated ML as a starting point and tune it further. Organizations can also use automated ML to benchmark their models.

Many Fortune 500 customers are benefiting from using automated ML. These include a global oil & refinery enterprise that’s using automated ML to forecast reservoir production and a medical devices company that’s using automated ML for predictive maintenance. Automated ML also powers Microsoft Power BI’s AI capabilities, where business analysts can build machine learning models without writing a single line of code.

What’s behind automated machine learning?


Azure Machine Learning service’s automated ML capability is based on a breakthrough from our Microsoft Research division and different from competing solutions in the market. The approach combines ideas from collaborative filtering and Bayesian optimization to search an enormous space of possible machine learning pipelines intelligently and efficiently. It's essentially a recommender system for machine learning pipelines. Similar to how streaming services recommend movies for users, automated ML recommends machine learning pipelines for data sets.

Azure Certification, Azure Guides, Azure Tutorial and Material, Azure Machine Learning Service

Streaming service (numbers represent user ratings for movies)

Azure Tutorial and Material, Azure Certification, Azure Learning, Azure Study Material

Automated ML (numbers represent accuracy of pipelines evaluated on datasets)

As indicated by the distributions shown on the right side of the figures above, automated ML also takes uncertainty into account, incorporating a probabilistic model to determine the best pipeline to try next. This approach allows automated ML to explore the most promising possibilities without exhaustive search, and to converge on the best pipelines for the user’s data faster than competing “brute force” approaches.
We trained automated ML’s probabilistic model by running hundreds of millions of experiments, each involving evaluation of a pipeline on a data set. This training allows automated ML to find good solutions quickly for your new problems. Automated ML continues to learn and improve today as it runs on new ML problems – even though it does not see your data. More about that next.

Design principles


At Microsoft our mission is to democratize machine learning by simplifying model building and improving the productivity of data scientists. We also place a strong emphasis on trust and data privacy. The principles behind automated ML seek to further the mission.

Data privacy

Automated ML is designed to generate pipelines without having to see the customer’s data, preserving privacy. Customer data and execution of the machine learning pipeline both live in the customer’s cloud subscription (or their local machine), which they have complete control of. Only the results of each pipeline run are sent back to the automated ML service, which then makes an intelligent, probabilistic choice of which pipelines should be tried next.

No need to “see” the data

Azure Certification, Azure Guides, Azure Tutorial and Material, Azure Machine Learning Service

Get started easily— Python SDK


Python is one of the most popular languages for building machine learning solutions due to the availability of numerous libraries such as numpy, matplotlib and machine learning frameworks such as scikit-learn, PyTorch, and TensorFlow. Users leverage all of these tools by downloading and installing libraries. Azure Machine Learning service uses the same paradigm— download and install the Azure Machine Learning service Python SDK which includes the automated ML capability. As a result, an intuitive and simple to use API is all it takes to run automated ML training jobs.

Bring to the IDEs that you are already familiar with


There are several Python development environments available for data scientists use. Those from a development background may prefer an IDE like PyCharm or VS Code. Data scientists who work with other team members may be using Jupyter Notebooks. Our goal is to bring automated ML to the development environments you use and are familiar with. Part of the Azure Machine Learning service Python SDK, automated ML works in any Python environment. All you need to do is download and install the SDK like any other Python libraries that you use. Automated ML has extensions for Jupyter Notebooks, which will help you visualize automated ML runs, monitor jobs, inspect stats without leaving the notebook environment.

Open source frameworks – sci-kit-learn, LightGBM


Machine Learning is innovating at very rapid pace thanks to an active open source community and rich set of open source frameworks. Many solutions today were simply unimaginable a few years ago. At Microsoft, our goal is to support popular frameworks and not get your organization locked into a proprietary framework. This helps organizations to innovate quickly without being stifled by proprietary frameworks.

Control and transparency


When building machine learning solutions, data scientists must inspect many attributes of machine learning models to and carefully weigh the trade-offs of each before choosing an optimal for a given business problem. Speed and automation versus accuracy, simple and interpretable versus complex and accurate, the list goes on. We want to provide complete control and transparency into all the models that automated ML generates so you can choose the best one for your scenario by making the tradeoffs that make sense for your business problem. The models and pipelines automated ML generates are regular Python pipelines that you are free to deconstruct and further tune.

Explore


We created automated ML to make machine learning more accessible for data scientists of all levels of experience.

Tuesday, 4 December 2018

Modernize your Java Spring Boot application with Azure Database for MySQL

Spring is a well-known Java-based framework for building web and enterprise applications addressing the modern business needs. One of the advantages of using the Spring Boot framework is that it simplifies the data access from relational and NoSQL data stores. Spring Boot framework with MySQL Database backend is one of the established patterns to meet the online transactional processing needs of business applications. The modern business applications are built and deployed on cloud native microservice platforms like Azure Kubernetes service (AKS) moving away from traditional monolithic design to meet the elastic scale and portability needs. The databases on the other hand have more stateful requirements with atomicity, consistency, durability, resiliency, and zero data loss across failures. It is therefore more suited to run databases outside of Kubernetes environment on managed database services like Azure Database for MySQL service which meets these requirements.

Developers and customers can easily build and deploy their Java Spring Boot microservices application in Azure platform thereby improving developer productivity and enabling businesses to achieve more with the following solutions.

◈ Azure DevOps, a developer platform to build automated and robust CI/CD pipelines.
◈ Azure Kubernetes Service, a managed Kubernetes platform.
◈ Azure Container Instance, a serverless container platform for running containerized solutions on Azure.
◈ Azure Database for MySQL, a fully managed, enterprise ready community MySQL database as a service, .

The following is a functional architecture sample of a Java Spring Boot microservices application called po-service on Azure. This Spring Boot application demonstrates how to build and deploy a purchase order microservice as a containerized application on Azure Kubernetes Service (AKS). The deployed microservice supports all CRUD operations on purchase orders.

Azure Study Materials, Azure Guides, Azure Certification, Azure Tutorial and Materials

To enable and integrate the microservices application running on Azure Kubernetes services with the database running on Azure Database for MySQL service, developers can utilize and leverage Open Service Broker for Azure together with Kubernetes Service Catalog.

We have published detailed step-by-step instructions to build and deploy the above architecture in our GitHub repository. The overall goal of this step-by-step guide is:

◈ To demonstrate the use of Open Service Broker for Azure to provision, deploy, and integrate Azure Database for MySQL from Azure Kubernetes Service seamlessly using the DevOps pipeline.
◈ To demonstrate the use of Helm (CLI) for deploying containerized applications on Kubernetes (AKS). Helm is a package manager for Kubernetes and is a part of CNCF. Helm is used for managing Kubernetes packages called Charts.
◈ To demonstrate how to secure a microservice (REST API) end-point using SSL/TLS (HTTPS transport) and expose it through the Ingress Controller addon on AKS.
◈ To demonstrate the serverless container solution by deploying the microservice on Azure Container Instances (ACI).

Sunday, 2 December 2018

Time series analysis in Azure Data Explorer

Azure Data Explorer (ADX) is a lightning fast service optimized for data exploration. It supplies users with instant visibility into very large raw datasets in near real-time to analyze performance, identify trends and anomalies, and diagnose problems.

Azure Data Explorer, Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning

ADX performs an on-going collection of telemetry data from cloud services or IoT devices. This data can then be analyzed for various insights such as monitoring service health, physical production processes, and usage trends. The analysis can be performed on sets of time series for selected metrics to find a deviation in the pattern of the metrics relative to their typical baseline patterns.

ADX contains native support for creation, manipulation, and analysis of time series. It empowers us to create and analyze thousands of time series in seconds and enable near real-time monitoring solutions and workflows. In this blog post, we are going to describe the basics of time series analysis in Azure Data Explorer.

Time series capabilities


The first step for time series analysis is to partition and transform the original telemetry table to a set of time series using the make-series operator. Using various functions, ADX then offers the following capabilities for time series analysis:

◈ Filtering – Used for noise reduction, smoothing, change detection, and pattern matching.
◈ Regression analysis – Used for trend change detection in streamed data.
◈ Seasonality detection – Used to automatically detect or validate seasonal or periodic patterns in each time series.
◈ Element-wise functions – Used to perform arithmetic and logical operations between two time series.

Example of a time series analysis query


The following query uses series_periods_detect and series_fit_line for time series analysis and discovery of periodic patterns and decreasing trends:

let min_t = toscalar(demo_many_series1 | summarize min(TIMESTAMP));
let max_t = toscalar(demo_many_series1 | summarize max(TIMESTAMP));
demo_many_series1
| make-series reads=avg(DataRead) on TIMESTAMP in range(min_t, max_t, 1h) by Loc, Op, DB
| where series_partial_sf(reads, 0) == false
| extend (p, ps)=series_periods_detect(reads, 0, 24, 1)
| mvexpand p to typeof(double), ps to typeof(double)
| where ps > 0.7
| extend series_fit_line(reads)
| top 2 by series_fit_line_reads_slope asc
| render timechart with(title='Top 2 Periodic Decreasing Web Service Traffic (out of 18,339 instances)')

In this query, Azure Data Explorer analyzes 18,339 time series of web service traffic and extracts those with a periodic pattern. Out of this subset, ADX looks for those instances with a decreasing trend. This entire processing takes only about one minute.

Azure Data Explorer, Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning