As the amount of data stored and queried continues to rise, it becomes increasingly important to have the most price-performant data warehouse. While we’re excited about being the industry leader in both of Gigaom’s TPC-H and TPC-DS benchmark reports, we don’t plan to stop innovating on behalf of our customers.
We’re excited to introduce several new features that will continue to make Azure SQL Data Warehouse the unmatched industry leader in price-performance, flexibility, and security.
To enable customers to continue improving the performance of their applications without adding any additional cost, we’re announcing preview availability of result-set caching, materialized views, and ordered clustered columnstore indexes.
In addition to price-performance enhancements, we’ve added new capabilities that enable customers to be more agile and flexible. The first is workload importance, which is a new feature that enables users to decide how workloads with conflicting needs get prioritized. Second, our new support for automatic statistics maintenance (auto-update statistics) means that manageability and maintenance of Azure SQL Data Warehouse just got easier and more effective. And finally, we’re also adding support for managing and querying JSON data. Users can now load JSON data directly into their data warehouses and mix it with other relational data, leading to faster and easier insights.
Our last announcement focuses on security and privacy. As you know, deploying data warehousing solutions in the cloud demands sophisticated and robust security. While Azure SQL Data Warehouse already enables an advanced security model to be deployed, today we’re announcing support for Dynamic Data Masking (DDM). DDM allows you to protect private data, through user-defined policies, ensuring it’s visible only to those that have permission to see it.



We’re excited to introduce several new features that will continue to make Azure SQL Data Warehouse the unmatched industry leader in price-performance, flexibility, and security.
To enable customers to continue improving the performance of their applications without adding any additional cost, we’re announcing preview availability of result-set caching, materialized views, and ordered clustered columnstore indexes.
In addition to price-performance enhancements, we’ve added new capabilities that enable customers to be more agile and flexible. The first is workload importance, which is a new feature that enables users to decide how workloads with conflicting needs get prioritized. Second, our new support for automatic statistics maintenance (auto-update statistics) means that manageability and maintenance of Azure SQL Data Warehouse just got easier and more effective. And finally, we’re also adding support for managing and querying JSON data. Users can now load JSON data directly into their data warehouses and mix it with other relational data, leading to faster and easier insights.
Our last announcement focuses on security and privacy. As you know, deploying data warehousing solutions in the cloud demands sophisticated and robust security. While Azure SQL Data Warehouse already enables an advanced security model to be deployed, today we’re announcing support for Dynamic Data Masking (DDM). DDM allows you to protect private data, through user-defined policies, ensuring it’s visible only to those that have permission to see it.
In the sections below, we’ll dive into these new features and the benefits that each provide.
Price-performance
Price-performance is a reoccurring theme in our releases because it ensures we provide one of the fastest analytics services at incredible value. With new functionalities announced today, we continue to demonstrate our commitment towards offering the leading price-performance platform.
Interactive dashboarding with result-set caching (preview)
Interactive dashboards come with predictable and repetitive query patterns. Result-set caching, now available in preview, helps with this scenario as it enables instant query response times while reducing time-to-insight for business analysts and reporting users.
With result-set caching enabled, Azure SQL Data Warehouse automatically caches results from repetitive queries, causing subsequent query executions to return results from the persisted cache that omits full query execution. In addition to saving compute cycles, queries satisfied by result-set cache do not use any concurrency slots and thus do not count against existing concurrency limits. For security reasons, only users with the appropriate security credentials can access the result sets in cache.
Materialized views to improve performance (preview)
Another new feature that greatly enhances query performance for a wide set of queries is materialized view support, now available in preview. A materialized view improves the performance of complex queries (typically queries with joins and aggregations) while offering simple maintenance operations.
When materialized views are created, Azure SQL Data Warehouse query optimizer transparently and automatically rewrites user queries to leverage deployed materialized views, leading to improved query performance. Best of all, as the data gets loaded into base tables, Azure SQL Data Warehouse automatically maintains and refreshes materialized views, providing a simplified view of maintenance and management. As the user queries leverage materialized views, queries run significantly faster and use less system resources. The more complex and expensive the query within the view is, the bigger potential there is for execution time savings.
Fast scans with ordered clustered columnstore indexes (preview)
Columnstore is a key enabler for storing and efficiently querying large amounts of data. For each table, it divides incoming data into row groups and each column of a row group forms a segment on a disk. When querying columnstore indexes, only the column segments that are relevant to user queries are read from the disk. Ordered clustered columnstore indexes further optimize query execution by enabling efficient segment elimination.
Due to pre-ordered data, you can drastically reduce the number of segments that are read from the disk, leading to faster query processing. Ordered clustered columnstore indexes is now available in preview, and queries containing filters and predicates can greatly benefit from this feature.
Flexibility
As business requirements evolve, the ability to change and adapt solution behavior is one of the key benefits of a modern data warehousing product. The ability to handle and manage heterogeneous data that enterprises have while offering ease of use and management is critical. To support these needs, Azure SQL Data Warehouse is introducing the following new functionalities to help you deal with ever-evolving requirements.
Prioritize workloads with workload importance (general availability)
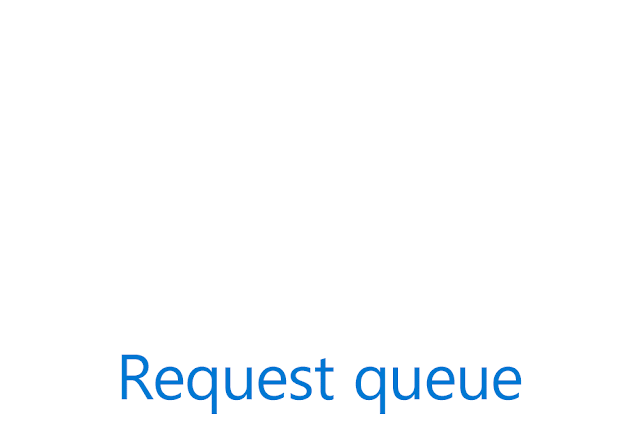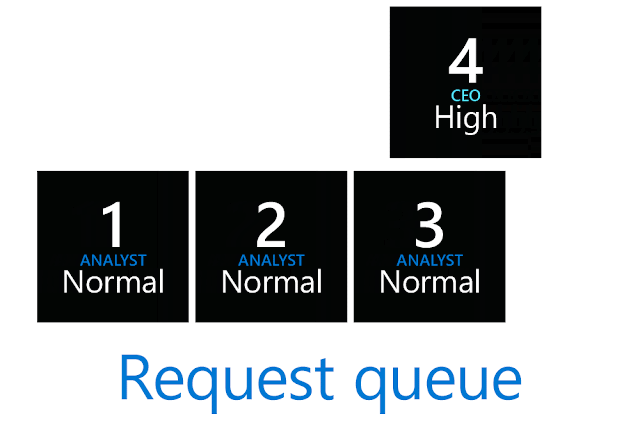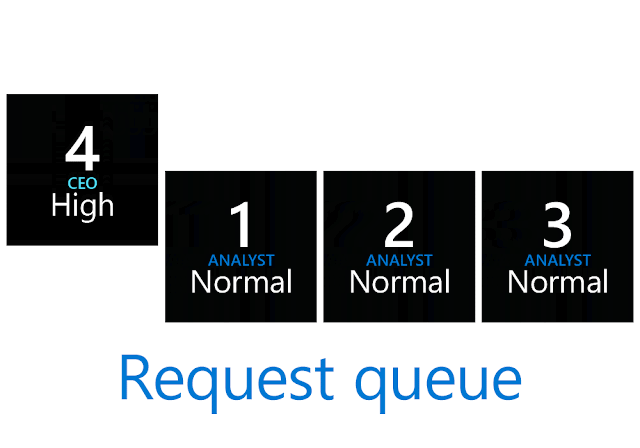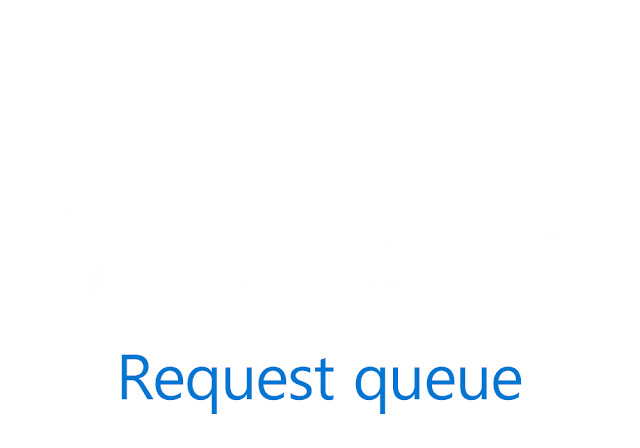
Running mixed workloads on your analytics solution is often a necessity to effectively and quickly execute business processes. In situations where resources are constrained, the capability to decide which workloads need to be executed first is critical, as it helps with overall solution cost management. For instance, executive dashboard reports may be more important than ad-hoc queries. Workload importance now enables this scenario. Requests with higher importance are guaranteed quicker access to resources, which helps meet predefined SLAs and ensures important requests are prioritized.
Workload classification concept
To define workload priority, various requests must be classified. Azure SQL Data Warehouse supports flexible classification policies that can be set for a SQL query, a database user, database role, Azure Active Directory login, or Azure Active Directory group. Workload classification is achieved using the new CREATE WORKLOAD CLASSIFIER syntax.
The diagram below illustrates the workload classification and importance function:
Workload importance concept
Workload importance is established through classification. Importance influences a requester's access to system resources including memory, CPU, and IO and locks. A request can be assigned one of these five levels of importance: low, below_normal, normal, above_normal, and high. If a request with above_normal importance is scheduled, it gets access to resources before a request with the default normal importance.

Manage and query JSON data (preview)
Organizations are increasingly faced with dealing with multiple data sources and heterogeneous file formats, JSON being among the top ones, aside from CSV files. To speed up time to insight and minimize unnecessary data transformation processes, Azure SQL Data Warehouse now enables support for querying JSON data. This feature is now available in preview.
Business analysts can now use the familiar T-SQL language to query and manipulate documents that are formatted as JSON data. JSON functions, such as JSON_VALUE, JSON_QUERY, JSON_MODIFY, and OPENJSON are now supported in Azure SQL Data Warehouse. Azure SQL Data Warehouse can now effectively support both relational and non-relational data, including joins between the two, while enabling users to use their traditional BI tools, such as Power BI.
Automatic statistics maintenance and update (preview)
Azure SQL Data Warehouse implements a cost-based optimizer to ensure optimal execution plans are being generated and used. For any cost-based optimizer to be effective, column level statistics are needed. When these statistics are stale, there is potential for selecting a non-optimal plan, leading to slower query performance.
Today, we’re extending that support for auto statistics creation by adding the ability to automatically refresh and maintain statistics. As data warehouse tables get loaded and updated, the system can now automatically detect and update out-of-date statistics. With the auto-update statistics capability now available in preview, Azure SQL Data Warehouse delivers full statistics management capabilities while simplifying statistics maintenance processes. You no longer need to manually maintain statistics, which leads to a simplified and more cost-effective data warehouse deployment.
Security
Azure SQL Data Warehouse provides one of the most advanced security and privacy features in the market. This is achieved through using proven SQL Server technology. SQL Server, as the core technology and component of Azure SQL Data Warehouse, has been the least vulnerable databases over the last eight years according to the NIST national vulnerabilities database. To expand existing Azure SQL Data Warehouse's security and privacy features, we’re announcing Dynamic Data Masking (DDM) support is now available in preview.
Protect sensitive data with dynamic data masking (preview)
Dynamic data masking (DDM) enables administrators and data developers to control access to their company’s data, allowing sensitive data to be safe and restricted. It prevents unauthorized access to private data by obscuring the data on-the-fly. Based on user-defined data masking policies, Azure SQL Data Warehouse can dynamically obfuscate data as the queries execute, and before results are shown to users.

Azure SQL Data Warehouse implements the DDM capability directly inside the engine. When creating tables with DDM, policies are stored in the system's metadata and then enforced by the engine as queries get executed. This centralized policy enforcement process simplifies data masking rules management as access control is not implemented and repeated at the application layer. As various users access queries tables, policies are automatically honored and applied while protecting sensitive data. DDM comes with flexible policies and you can choose to define a partial mask, which exposes some of the data in the selected columns, or a full mask that obfuscates the data completely. Azure SQL Data Warehouse also provides built-in masking functions that users can choose from.


 Posts

