Monday, 11 March 2019

HDInsight Metastore Migration Tool open source release now available

We are excited to share the release of the Microsoft Azure HDInsight Metastore Migration Tool (HMMT), an open-source script that can be used for applying bulk edits to the Hive metastore.

The HDInsight Metastore Migration Tool is a low-latency, no-installation solution for challenges related to data migrations in Azure HDInsight. There are many reasons why a Hive data migration may need to take place. You may need to protect your data by enabling secure transfer on your Azure storage accounts. Perhaps you will be migrating your Hive tables from WASB to Azure Data Lake Storage (ADLS) Gen2 as part of your upgrade from HDInsight 3.6 to 4.0. Or you may have decided to organize the locations of your databases, tables, and user-defined functions (UDF) to follow a cohesive structure. With HMMT, these migration scenarios and many others no longer require manual intervention.

HMMT handles Hive metadata migration scenarios in a quick, safe, and controllable environment. This blog post is divided into three sections. First, the background to HMMT is outlined with respect to the Hive metastore and Hive storage patterns. The second section covers the design of HMMT and describes initial setup steps. Finally, some sample migrations are described and solved with HMMT as a demonstration of its usage and value.

Background


The Hive metastore

The Hive metastore is a SQL database for Hive metadata such as table, database, and user defined function storage locations. The Hive metastore is provisioned automatically when an HDInsight cluster is created. Alternatively, an existing SQL database may be used to persist metadata across multiple clusters. The existing SQL database is then referred to as an external metastore. HMMT is intended to be used against external metastores to persist metadata migrations over time and across multiple clusters.

Hive storage uniform resource identifiers
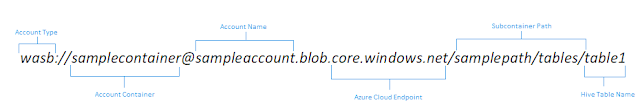
Azure Certifications, Azure Guides, Azure Study Materials, Azure Learning

For each Hive table, database, or UDF available to the cluster, the Hive metastore keeps a record of that artifact’s location in external storage. Artifact locations are persisted in a Windows Azure Storage Blob or in Azure Data Lake Storage. Each location is represented as an Azure storage uniform resource identifier (URI), which describes the account-type, account, container, and subcontainer path that the artifact lives in. The above diagram describes the schema used to represent Hive table URIs. The same schema pattern applies to Hive databases and UDFs. 

Suppose a Hive query is executed against table1. Hive will first attempt to read the table contents from the corresponding storage entry found in the Hive metastore. Hive supports commands for displaying and updating a table’s storage location:

Azure Certifications, Azure Guides, Azure Study Materials, Azure Learning

Changing the storage location of a table requires the execution of an update command corresponding to the table of interest. If multiple table locations are to be changed, multiple update commands must be executed. Since storage locations must be updated manually, wholesale changes to the metastore can be an error-prone and time-consuming task. The location update story concerning non-table artifacts is even less favorable - the location of a database or UDF cannot be changed from within Hive. Therefore, the motivation behind releasing HMMT to the public is to provide a pain-free way to update the storage location of Hive artifacts. HMMT directly alters the Hive metastore, which is the fastest (and only) way to make changes to Hive artifacts at scale.

How HMMT works


HMMT generates a series of SQL commands that will directly update the Hive metastore based on the input parameters. Only storage URIs that match the input parameters will be affected by the script. The tool can alter any combination of Hive storage accounts, account-types, containers, and subcontainer paths. Note that HMMT is exclusively supported on HDInsight 3.6 and onwards.

Start using HMMT right away by downloading it directly from the Microsoft HDInsight GitHub page. HMMT requires no installation. Make sure the script itself is run from an IP address that is whitelisted to the Hive metastore SQL Server. HMMT can be run from any UNIX command-line that has one of the supported query clients installed. The script does not necessarily need to be run from within the HDInsight cluster. Initially supported clients are Beeline and SqlCmd. Since Beeline is supported, HMMT can be run directly from any HDInsight cluster headnode.

Disclaimer: Since HMMT directly alters the contents of the Hive metastore, it is recommended to use the script with caution and care. When executing the script, the post-migration contents of the metastore will be shown as console output in order to describe the potential impact of the execution. For the specified migration parameters to take effect, the flag “liverun” must be passed to the HMMT command. The tool launches as a dry run by default. In addition, it is strongly recommended to keep backups of the Hive metastore even if you do not intend to use HMMT. More information regarding Hive metastore backups can be found at the end of this blog.

Usage examples


HMMT supports a wide variety of use cases related to the migration and organization of Hive metadata. The benefit of HMMT is that the tool provides an easy way to make sure that the Hive metastore reflects the results of a data migration. HMMT may also be executed against a set of artifacts in anticipation of an upcoming data migration. This section demonstrates the usage and value of HMMT using two examples. One example will cover a table migration related to secure storage transfer, and the other will describe the process to migrate Hive UDF JAR metadata.

Example 1: Enabling secure transfer

Suppose your Hive tables are stored across many different storage accounts, and you have recently enabled secure transfer on a selection of these accounts. Since enabling secure transfer does not automatically update the Hive metastore, the storage URIs must be modified to reflect the change (for example, from WASB to WASBS). With your IP whitelisted and a supported client installed, HMMT will update all matching URIs with the following command:

Azure Certifications, Azure Guides, Azure Study Materials, Azure Learning

◈ The first four arguments passed to the script correspond to the SQL server, database, and credentials used to access the metastore.

◈ The next four arguments correspond to the ‘source’ attributes to be searched for. In this case the script will affect WASB accounts Acc1, Acc2 and Acc3. There will be no filtering for the container or subcontainer path. HMMT supports WASB, WASBS, ABFS, ABFSS, and ADL as storage migration options.

◈ The target flag represents the table in the Hive metastore to be changed. The table SDS stores Hive table locations. Other table options include DBS for Hive databases, FUNC_RU for Hive UDFs, and SKEWED_COL_VALUE_LOC_MAP for a skewed store of Hive tables.

◈ The Query Client flag corresponds to the query command line tool to be used. In this case, the client of choice is Apache Beeline.

The remaining flags correspond to the ‘destination’ attributes for affected URIs. In this case, all matching URIs specified by the source options will have their account type moved to WASBS. Up to one entry per destination flag is permitted. The values of these flags are merged together to form the post-migration URI pattern.

This sample script command will only pick up table URIs corresponding to WASB accounts, where the account name is “Acc1”, “Acc2”, or “Acc3.” The container and path options are left as a wildcard, meaning that every table under any of these three accounts will have its URI adjusted. The adjustment made by the script is to set the storage type to WASBS. No other aspects of the table URIs will be affected.

Example 2: UDF JAR organization

In this example, suppose you have loaded many UDFs into Hive over time. UDFs are implemented in JAR files, which may be stored in various account containers depending on which cluster the JAR was introduced from. As a result, the table FUNC_RU will have many entries across a variety of account containers and paths. If you wanted to clean up the locations of UDF JARs, you could do so using this command:

Azure Certifications, Azure Guides, Azure Study Materials, Azure Learning

This command will pick up UDF JAR URIs, which are exclusively found in the table FUNC_RU, in the WASB storage account “Acc1” for any container and subcontainer path. Once the script is complete, the Hive metastore will show that all JARs from that account can be found in the /jarfiles/ directory under the container “jarstoragecontainer."

Saturday, 9 March 2019

Real-time serverless applications with the SignalR Service bindings in Azure Functions

Since our public preview announcement at Microsoft Ignite 2018, every month thousands of developers worldwide have leveraged the Azure SignalR Service bindings for Azure Functions to add real-time capabilities to their serverless applications. Today, we are excited to announce the general availability of these bindings in all global regions where Azure SignalR Service is available!

SignalR Service is a fully managed Azure service that simplifies the process of adding real-time web functionality to applications over HTTP. This real-time functionality allows the service to push messages and content updates to connected clients using technologies such as WebSocket. As a result, clients are updated without the need to poll the server or submit new HTTP requests for updates.

Azure Certification, Azure Guides, Azure Study Materials, Azure Learning

Azure Functions provides a productive programming model based on triggers and bindings for accelerated development and serverless hosting of event-driven applications. It enables developers to build apps using the programming languages and tools of their choice, with an end-to-end developer experience that spans from building and debugging locally, to deploying and monitoring in the cloud. Combining Azure SignalR Service with Azure Functions using these bindings, you can easily push updates to the UI of your applications with just a few lines of code. The source of those updates can be data coming from different Azure services, or any service able to communicate over HTTP, thanks to the triggers supported in Azure Functions that will start the execution of a script responding to an event.

A common scenario worth mentioning is updating the UI of an application based on modifications made on the database. Using a combination of Cosmos DB change feed, Azure Functions, and SignalR Service, you can automate these UI updates in real-time with just a few lines of code for registering the client that will receive those updates and pushing the updates themselves. This fully managed experience is a great fit for event-driven scenarios and enables the creation of serverless backends and applications with real-time capabilities, reducing development time and operations overhead.

Azure Certification, Azure Guides, Azure Study Materials, Azure Learning

Using the Azure SignalR Service bindings for Azure Functions you will be able to:

◈ Use SignalR Service without dependency on any application server for a fully managed, serverless experience.

◈ Build serverless real-time applications using all Azure Functions generally available languages: JavaScript, C#, and Java.

◈ Leverage the SignalR Service bindings with all event triggers supported by Azure Functions to push messages to connected clients in real-time.

◈ Use App Service Authentication with SignalR Service and Azure Functions for improved security and out-of-the-box, fully managed authentication.

Friday, 8 March 2019

Azure Databricks – New capabilities at lower cost

Azure Databricks provides a fast, easy, and collaborative Apache Spark™-based analytics platform to accelerate and simplify the process of building big data and AI solutions backed by industry leading SLAs.

With Azure Databricks, customers can set up an optimized Apache Spark environment in minutes. Data scientists and data engineers can collaborate using an interactive workspace with languages and tools of their choice. Native integration with Azure Active Directory (Azure AD) and other Azure services enables customers to build end-to-end modern data warehouse, machine learning and real-time analytics solutions.

We have seen tremendous adoption of Azure Databricks and today we are excited to announce new capabilities that we are bringing to market.

General availability of Data Engineering Light


Customers can now get started with Azure Databricks with a new low-priced workload called Data Engineering Light that enables customers to run batch applications on managed Apache Spark. It is meant for simple, non-critical workloads that don’t need the performance, autoscaling, and other benefits provided by Data Engineering and Data Analytics workloads.

Additionally, we have reduced the price for the Data Engineering workload across both the Standard and Premium SKUs. Both the SKUs are now available at up to 25 percent lower cost.

Preview of managed MLflow


MLflow is an open source framework for managing the machine learning lifecycle. With managed MLflow, customers can access it natively from their Azure Databricks environment and leverage Azure Active Directory for authentication. With managed MLflow on Azure Databricks customers can:

◈ Track experiments by automatically recording parameters, results, code, and data to an out-of-the-box hosted MLflow tracking server. Runs can now be organized in experiments from within the Azure Databricks, and results can be queried from within the Azure Databricks notebooks to identify the best performing models.

◈ Package machine learning code and dependencies locally in a reproducible project format and execute remotely on a Databricks cluster.

◈ Quickly deploy models to production.

Machine learning on Azure with Azure Machine Learning and Azure Databricks


Since the general availability of Azure Machine Learning service (AML) in December 2018, and its integration with Azure Databricks, we have received overwhelmingly positive feedback from customers who are using this combination to accelerate machine learning on big data. Azure Machine Learning complements the Azure Databricks experience by:

◈ Unlocking advanced automated machine learning capability which enables data scientists of all skill levels to identify suitable algorithms and hyperparameters faster.

◈ Enabling DevOps for machine learning for simplified management, monitoring, and updating of machine learning models.

◈ Deploying models from the cloud and the edge.

◈ Providing a central registry for experiments, machine learning pipelines, and models that are being created across the organization.

The combination of Azure Databricks and Azure Machine Learning makes Azure the best cloud for machine learning. Customers benefit from an optimized, autoscaling Apache Spark based environment, an interactive collaborate workspace, automated machine learning, and end-to-end Machine Learning Lifecycle management.

Azure Databricks, Azure Tutorial and Material, Azure Learning, Azure Study Materials

Wednesday, 6 March 2019

Scaling out read workloads in Azure Database for MySQL

For read-heavy workloads that you are looking to scale out, you can use read replicas, which are now generally available to all Azure Database for MySQL users. Read replicas make it easy to horizontally scale out beyond a single database server. This is useful in workloads such as BI reporting and web applications, which tend to have more read operations than write.

The feature supports continuous asynchronous replication of data from one Azure Database for MySQL server (the “master” server) to up to five Azure Database for MySQL servers (the “read replica” servers) in the same region. Read-heavy workloads can be distributed across the replica servers according to your preference. Replica servers are read-only except for writes replicated from data changes on the master.

What’s supported with read replicas?


You can create or delete replica servers based on your workload’s needs. A master server can support up to five replica servers within the same Azure region. Stopping replication to any replica server makes it a standalone read-write server.

You can easily manage your replica servers using the Azure portal and Azure CLI.

From the Azure portal:

Microsoft Tutorial and Material, Azure Certifications, Azure Learning, Azure Guides

Use Azure Monitor to track replication with the “replication lag in seconds” metric:

Microsoft Tutorial and Material, Azure Certifications, Azure Learning, Azure Guides

From the Azure CLI:

az mysql server replica create -n mydemoreplica1 -g myresourcegroup -s mydemomaster

Below are some application patterns used by our customers and partners that leverage read replicas for scaling workloads.

BI reporting


Data from disparate data sources is processed every few minutes and loaded into the master server. The master server is dedicated for loads and processing, not directly exposing it to BI users for reporting or analytics to ensure predictable performance. The reporting workload is scaled out across multiple read replicas to manage high user concurrency with low latency.

Microsoft Tutorial and Material, Azure Certifications, Azure Learning, Azure Guides

Microservices


In this architecture pattern, the application is broken into multiple microservices, with data modification APIs connecting to the master server while reporting APIs connect to read replicas. The data modification APIs are prefixed with “Set-”, while reporting APIs are prefixed with “Get-“. The load balancer is used to route the traffic based on the API prefix.

Microsoft Tutorial and Material, Azure Certifications, Azure Learning, Azure Guides

Friday, 1 March 2019

Introducing Microsoft Azure Sentinel, intelligent security analytics for your entire enterprise

Security can be a never-ending saga—a chronicle of increasingly sophisticated attacks, volumes of alerts, and long resolution timeframes where today’s Security Information and Event Management (SIEM) products can’t keep pace.

SecOps teams are inundated with a very high volume of alerts and spend far too much time in tasks like infrastructure set up and maintenance. As a result, many legitimate threats go unnoticed. An expected shortfall of 3.5M security professionals by 2021 will further increase the challenges for security operations teams. You need a solution that empowers your existing SecOps team to see the threats clearer and eliminate the distractions.

That’s why we reimagined the SIEM tool as a new cloud-native solution called Microsoft Azure Sentinel. Azure Sentinel provides intelligent security analytics at cloud scale for your entire enterprise. Azure Sentinel makes it easy to collect security data across your entire hybrid organization from devices, to users, to apps, to servers on any cloud.  It uses the power of artificial intelligence to ensure you are identifying real threats quickly and unleashes you from the burden of traditional SIEMs by eliminating the need to spend time on setting up, maintaining, and scaling infrastructure. Since it is built on Azure, it offers nearly limitless cloud scale and speed to address your security needs. Traditional SIEMs have also proven to be expensive to own and operate, often requiring you to commit upfront and incur high cost for infrastructure maintenance and data ingestion. With Azure Sentinel there are no upfront costs, you pay for what you use.

Many enterprises are using Office 365 and are increasingly adopting the advanced security and compliance offerings included in Microsoft 365. There are many cases when you want to combine security data from users and end point applications with information from your infrastructure environment and third-party data to understand a complete attack.

It would be ideal if you could do this all within the compliance boundaries of a single cloud provider. Today we are announcing that you can bring your Office 365 activity data to Azure Sentinel for free. It takes just a few clicks and you retain the data within the Microsoft cloud.

“With Microsoft Azure Sentinel, we can better address the main SIEM landscape challenges for our clients, along with simplifying data residency and GDPR concerns.”.

Azure Certifications, Azure Learning, Azure Tutorial and Materials, Azure Guides

Let’s look at how Azure Sentinel will help you deliver cloud-native security operations:

Collect data across your enterprise easily – With Azure Sentinel you can aggregate all security data with built-in connectors, native integration of Microsoft signals, and support for industry standard log formats like common event format and syslog. In just a few clicks you can import your Microsoft Office 365 data for free and combine it with other security data for analysis. Azure Sentinel uses Azure Monitor which is built on a proven and scalable log analytics database that ingests more than 10 petabytes every day and provides a very fast query engine that can sort through millions of records in seconds.

We continue to collaborate with many partners in the Microsoft Intelligent Security Association. Azure Sentinel connects to popular solutions including Palo Alto Networks, F5, Symantec, Fortinet, and Check Point with many more to come. Azure Sentinel also integrates with Microsoft Graph Security API, enabling you to import your own threat intelligence feeds and customizing threat detection and alert rules. There are custom dashboards that give you a view optimized for your specific use-case.

Adam Geller, Senior Vice President, SaaS, virtualization, and cloud-delivered security of Palo Alto Networks said, “We’re pleased with our ongoing collaboration with Microsoft and the work we’re doing to deliver greater security orchestration for our joint customers. This latest integration allows customers to forward their physical and virtualized next generation firewall logs to Azure Sentinel and use custom dashboards and artificial intelligence to rapidly uncover potential security incidents. Palo Alto Networks customers can also extend AutoFocus and other third-party threat intelligence to Azure Sentinel via our new integration between MineMeld and the Microsoft Graph Security API.”

Analyze and detect threats quickly with AI on your side – Security analysts face a huge burden from triaging as they sift through a sea of alerts, and correlate alerts from different products manually or using a traditional correlation engine. That’s why Azure Sentinel uses state of the art, scalable machine learning algorithms to correlate millions of low fidelity anomalies to present a few high fidelity security incidents to the analyst. ML technologies will help you quickly get value from large amounts of security data you are ingesting and connect the dots for you. For example, you can quickly see a compromised account that was used to deploy ransomware in a cloud application. This helps reduce noise drastically, in fact we have seen an overall reduction of up to 90 percent in alert fatigue during evaluations. Early adopters are seeing the benefits of threat detections with AI. Reed M. Wiedower, CTO of New Signature said, “We see a huge value with Azure Sentinel because of its ability to generate insights across a vast array of different pieces of infrastructure.”

These built-in machine learning models are based on the learnings from the Microsoft security team over many years of defending our customer’s cloud assets. You do not need to be a data scientist to leverage use these benefits you just turn them on. Of course, if you are a data scientist and you want to customize and enrich the detections then you can bring your own models to Azure Sentinel using the built-in Azure Machine Learning service. Additionally, Azure Sentinel can connect to user activity and behavior data from Microsoft 365 security products which can be combined with other sources to provide visibility into an entire attack sequence.

Investigate and hunt for suspicious activities – Graphical and AI-based investigation will reduce the time it takes to understand the full scope of an attack and its impact. You can visualize the attack and take quick actions in the same dashboard.  

Azure Certifications, Azure Learning, Azure Tutorial and Materials, Azure Guides

Proactive hunting of suspicious activities is another critical task for the security analysts. Often the process by which SecOps collect and analyze the data is a repeatable process which can be automated. Today, Azure Sentinel provides two capabilities that enable you to automate your analysis by building hunting queries and Azure Notebooks that are based on Jupyter notebooks. We have developed a set of queries and Azure Notebooks based on the proactive hunting that Microsoft’s Incident Response and Threat Analysts teams perform. As the threat landscape evolves, so will our queries and Azure Notebooks. We will provide new queries and Azure Notebooks via the Azure Sentinel GitHub community.

Automate common tasks and threat response – While AI sharpens your focus on finding problems, once you have solved the problem you don’t want to keep finding the same problems over and over – rather you want to automate response to these issues. Azure Sentinel provides built-in automation and orchestration with pre-defined or custom playbooks to solve repetitive tasks and to respond to threats quickly. Azure Sentinel will augment existing enterprise defense and investigation tools, including best-of-breed security products, homegrown tools, and other systems like HR management applications and workflow management systems like ServiceNow.

Azure Certifications, Azure Learning, Azure Tutorial and Materials, Azure Guides

Microsoft’s unparalleled threat intelligence that is informed by analyzing 6.5+ trillions of signals daily and decades of security expertise at cloud scale will help you modernize your security operations.

“Azure Sentinel provides a proactive and responsive cloud-native SIEM that will help customers simplify their security operations and scale as they grow.”

Security doesn’t have to be an endless saga. Instead, put the cloud and large-scale intelligence to work. Make your threat protection smarter and faster with artificial intelligence. Import Microsoft Office 365 data for security analytics for free.

Announcing the general availability of Azure Lab Services

We are very excited to announce the general availability of Azure Lab Services - your computer labs in the cloud.

With Azure Lab Services, you can easily set up and provide on-demand access to preconfigured virtual machines (VMs) to teach a class, train professionals, run hackathons or hands-on labs, and more. Simply input what you need in a lab and let the service roll it out to your audience. Your users go to a single place to access all their VMs across multiple labs, and connect from there to learn, explore, and innovate.

Since our preview announcement, we have had many customers use the service to conduct classes, training sessions, boot camps, hands on labs, and more! For classroom or professional training, you can provide students with a lab of virtual machines configured with exactly what you need for class and give each student a specified number of hours to use the VMs for homework or personal projects. You can run a hackathon or a hands-on lab at conferences or events and scale up to hundreds of virtual machines for your attendees. You can also create an invite-only private lab of virtual machines installed with your prerelease software to give preview customers access to early trials or set up interactive sales demos.

Top three reasons customers use Azure Lab Services


Automatic management of Azure infrastructure and scale

Azure Lab Services is a managed service, which means that provisioning and management of a lab’s underlying infrastructure is handled automatically by the service. You can just focus on preparing the right lab experience for your users. Let the service handle the rest and roll out your lab’s virtual machines to your audience. Scale your lab to hundreds of virtual machines with a single click.

Azure Lab Services, Azure Tutorial and Materials, Azure Certifications, Azure Learning

Simple experience for your lab users

Users who are invited to your lab get immediate access to the resources you give them inside your labs. They just need to sign in to see the full list of virtual machines they have access to across multiple labs. They can click on a single button to connect to the virtual machines and start working. Users don’t need Azure subscriptions to use the service.

Azure Lab Services, Azure Tutorial and Materials, Azure Certifications, Azure Learning

Cost optimization and tracking 

Keep your budget in check by controlling exactly how many hours your lab users can use the virtual machines. Set up schedules in the lab to allow users to use the virtual machines only during designated time slots or set up reoccurring auto-shutdown and start times. Keep track of individual users’ usage and set limits.

Azure Lab Services, Azure Tutorial and Materials, Azure Certifications, Azure Learning

Saturday, 23 February 2019

PyTorch on Azure: Deep learning in the oil and gas industry

Drilling for oil and gas is one of the most dangerous jobs on Earth. Workers are exposed to the risk of events ranging from small equipment malfunctions to entire off shore rigs catching on fire. Fortunately, the application of deep learning in predictive asset maintenance can help prevent natural and human made catastrophes.

Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning

We have more information than ever on our equipment thanks to sensors and IoT devices, but we are still working on ways to process the data so it is valuable for preventing these catastrophic events. That’s where deep learning comes in. Data from multiple sources can be used to train a predictive model that helps oil and gas companies predict imminent disasters, enabling them to follow a proactive approach.

Using the PyTorch deep learning framework on Microsoft Azure, Accenture helped a major oil and gas company implement such a predictive asset maintenance solution. This solution will go a long way in protecting their staff and the environment.

What is predictive asset maintenance?


Predictive asset maintenance is a core element of the digital transformation of chemical plants. It is enabled by an abundance of cost-effective sensors, increased data processing, automation capabilities, and advances in predictive analytics. It involves converting information from both real-time and historical data into simple, accessible, and actionable insights. This is in order to enable the early detection and elimination of defects that would otherwise lead to malfunction. For example, by simply detecting an early defect in a seal that connects the pipes, we can prevent a potential failure that can result in a catastrophic collapse of the whole gas turbine.

Under the hood, predictive asset maintenance combines condition-based monitoring technologies, statistical process control, and equipment performance analysis to enable data from disparate sources across the plant to be visualized clearly and intuitively. This allows operations and equipment to be better monitored, processes to be optimized, better controlled, and energy management to be improved.

It is worth noting that the predictive analytics at the heart of this process do not tell the plant operators what will happen in the future with complete certainty. Instead, they forecast what is likely to happen in the future with an acceptable level of reliability. It can also provide “what-if” scenarios and an assessment of risks and opportunities.

Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning

Figure 1 – Asset maintenance maturity matrix (Source: Accenture)

The challenge with oil and gas

Event prediction is one of the key elements in predictive asset maintenance. For most prediction problems there are enough examples of each pattern to create a model to identify them. Unfortunately, in certain industries like oil and gas where everything is geared towards avoiding failure, the sought-after examples of failure patterns are rare. This means that most standard modelling approaches either perform no better than experienced humans or fail to work at all.

Accenture’s solution with PyTorch and Azure

Although there only exists a small number of failure examples, there exists a wealth of times series and inspection data that can be leveraged.

Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning

Figure 2 – Approach for Predictive Maintenance (Source : Accenture)

After preparing the data in stage one, a two-phase deep learning solution was built with PyTorch in stage two. First, a recurrent neural network (RNN) was trained in combination with a long short-term memory (LSTM) architecture which is phase one of stage two. The neural network architecture used in the solution was inspired by Koprinkova-Hristova et al 2011 and Aydin and Guldamlasioglu 2017. This RNN timeseries model forecasts important variables, such as the temperature of an important seal. These forecasts are then fed into a classifier algorithm (random forest) to identify the variable is outside of the safe range and if so, the algorithm produces a ranking of potential causes which experts can examine and address. This effectively enables experts to address the root causes of potential disasters before they occur.

The following is a diagram of the system that was used for training and execution of the solution:  

Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning

Figure 3 - System Architecture

The architecture above was chosen to ensure the customer requirement of maximum flexibility in modeling, training, and in the execution of complex machine learning workflows are using Microsoft Azure. At the time of implementation, the services that fit these requirements were HDInsights and Data Science Virtual Machines (DSVM). If the project was implemented today, Azure Machine Learning service would have been used for training/inferencing with HDInsights or Azure Databricks for data processing.

PyTorch was used due to the extreme flexibility in designing the computational execution graphs, and not being bound into a static computation execution graph like in other deep learning frameworks. Another important benefit of PyTorch is that standard python control flow can be used and models can be different for every sample. For example, tree-shaped RNNs can be created without much effort. PyTorch also enables the use of Python debugging tools, so programs can be stopped at any point for inspection of variables, gradients, and more. This flexibility was very beneficial during training and tuning cycles.

The optimized PyTorch solution resulted in faster training time by over 20 percent compared to other deep learning frameworks along with 12 percent faster inferencing. These improvements were crucial in the time critical environment that team was working in. Please note, that the version tested was PyTorch 0.3.

Overview of benefits of using PyTorch in this project:

◈ Training time
     ◈ Reduction in average training time by 22 percent using PyTorch on the outlined Azure architecture.
◈ Debugging/bug fixing
     ◈ The dynamic computational execution graph in combination with Python standard features reduced the overall development time by 10 percent.
◈ Visualization
     ◈ The direct integration into Power BI enabled a high end-user acceptance from day one.
◈ Experience using distributed training
     ◈ The dynamic computational execution graph in combination with flow control allowed us to create a simple distributed training model and gain significant improvements in overall training time.

How did Accenture operationalize the final model?


Scalability and operationalization were key design considerations from day one of the project, as the customer wanted to scale out the prototype to several other assets across the fleet. As a result, all components within the system architecture were chosen with those as criteria. In addition, the customer wanted to have the ability to add more data sources using Azure Data Factory. Azure Machine Learning service and its model management capability were used to operationalize the final model. The following diagram illustrates the deployment workflow used.

Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning

Figure 4 – Deployment workflow

The deployment model was also integrated into a Continuous Integration/Continuous Delivery (CI/CD) workflow as depicted below.

Azure Certification, Azure Tutorial and Material, Azure Guides, Azure Learning

PyTorch on Azure: Better together


The combination of Azure AI offerings with the capabilities of PyTorch proved to be a very efficient way to train and rapidly iterate on the deep learning architectures used for the project. These choices yielded a significant reduction in training time and increased productivity for data scientists.

Azure is committed to bringing enterprise-grade AI advances to developers using any language, any framework, and any development tool. Customers can easily integrate Azure AI offerings into any part of their machine learning lifecycles to productionize their projects at scale, without getting locked into any one tool or platform.